
Explore Metergraph
Let’s explore what Metergraph can do by looking at an example.
Cascade Marmot is a fictional competitive-research company. Its product runs eight AI agent workflows and spends about $12,700 a month on LLM calls. Below, its team goes from finding where that money goes to a cheaper setup it can trust. Every screenshot comes from a demo workspace with Cascade Marmot’s data.
1. Where is the money going?
Section titled “1. Where is the money going?”Spot · Performance
Let’s understand what is working, what is not, and what is expensive. Start on Performance.
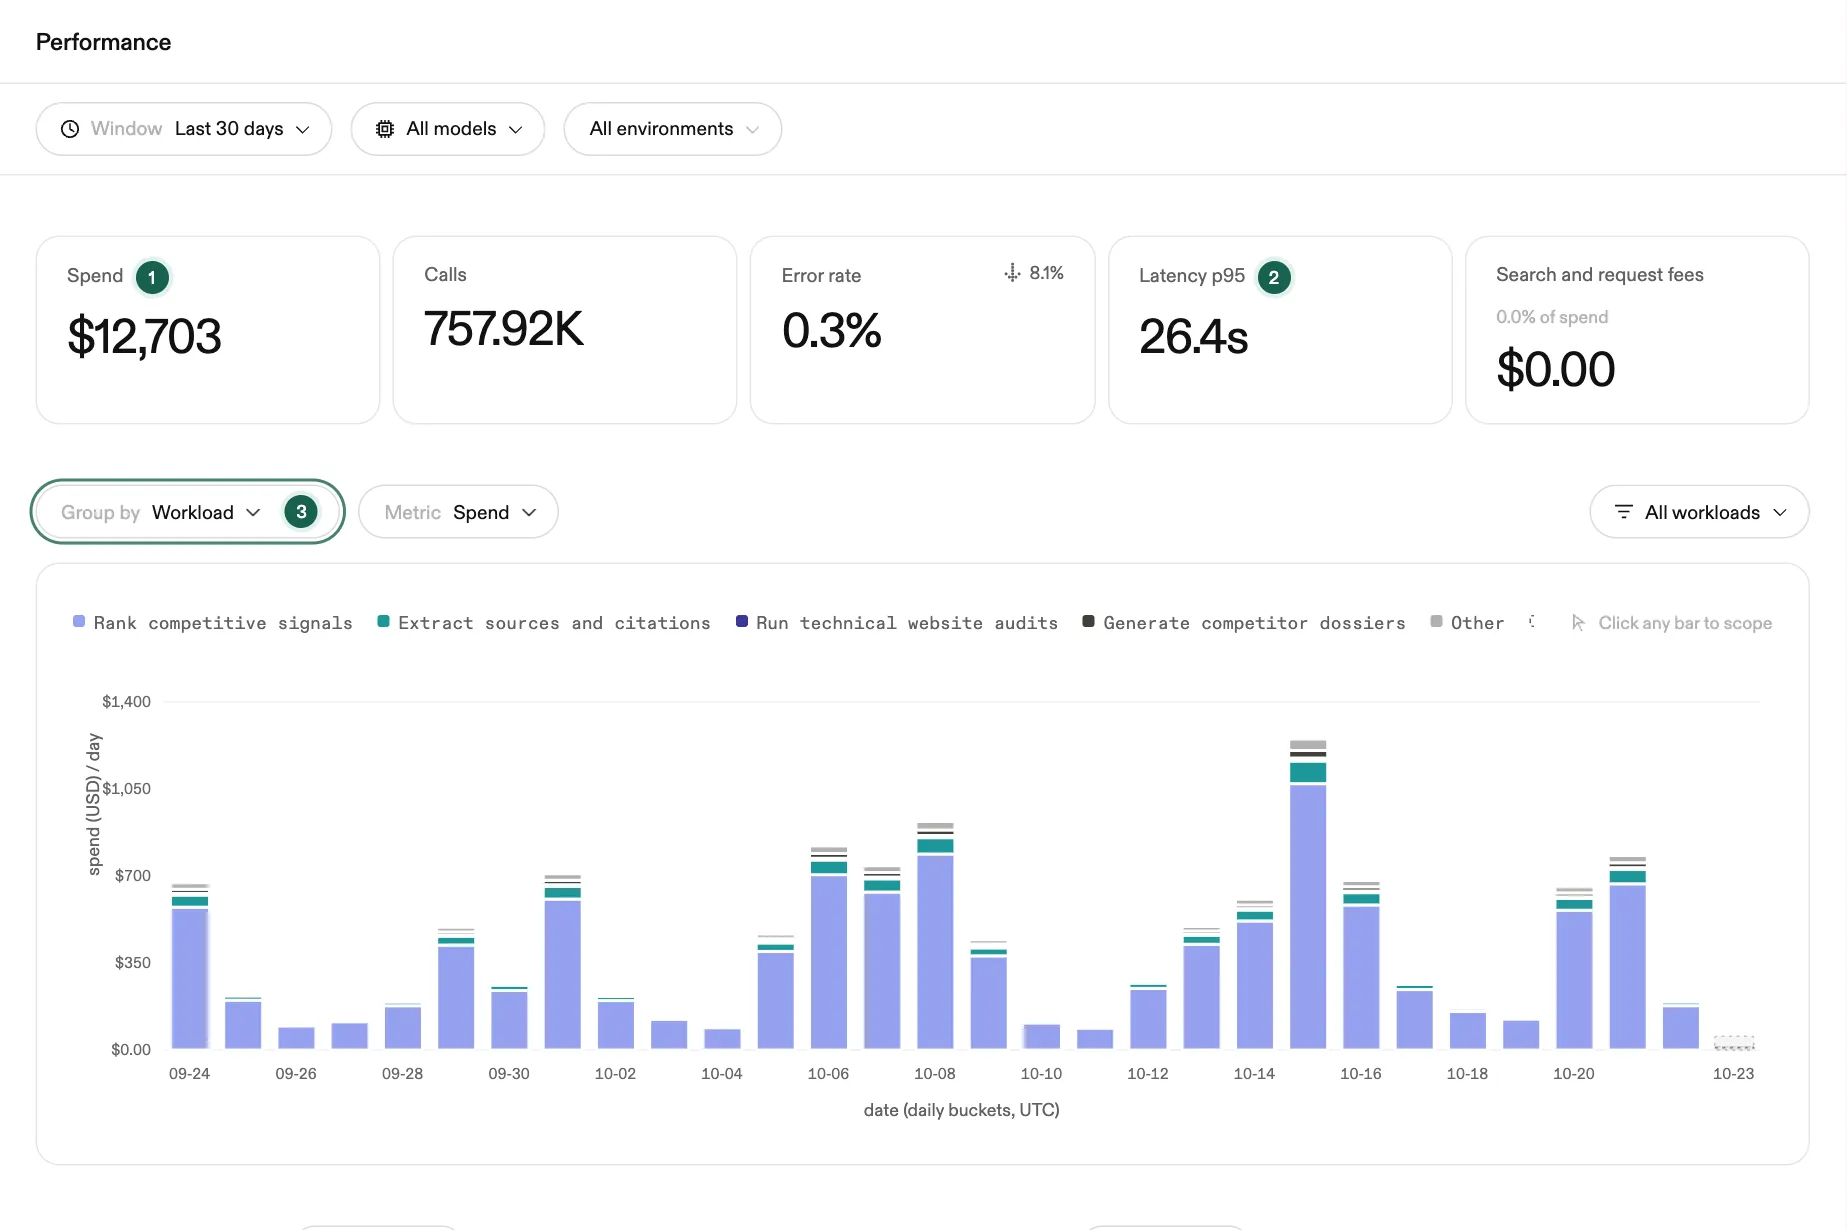
- Spend for the window: $12,703 over 30 days. Each call is priced from the model catalog when it arrives.
- Latency p95: 95% of calls finish within 26.4 seconds. Watch the p95 rather than the average: slow tails are what users feel.
- Group by splits the chart by provider, model, or workload. Here it is set to workload.
With your traffic: send your first trace or import existing traces.
2. What is that workflow actually doing?
Section titled “2. What is that workflow actually doing?”Understand · Workloads
Open the workload to see one agent workflow on its own: what it costs, how it behaves, and which models it runs on, with the calls behind it one tab away.
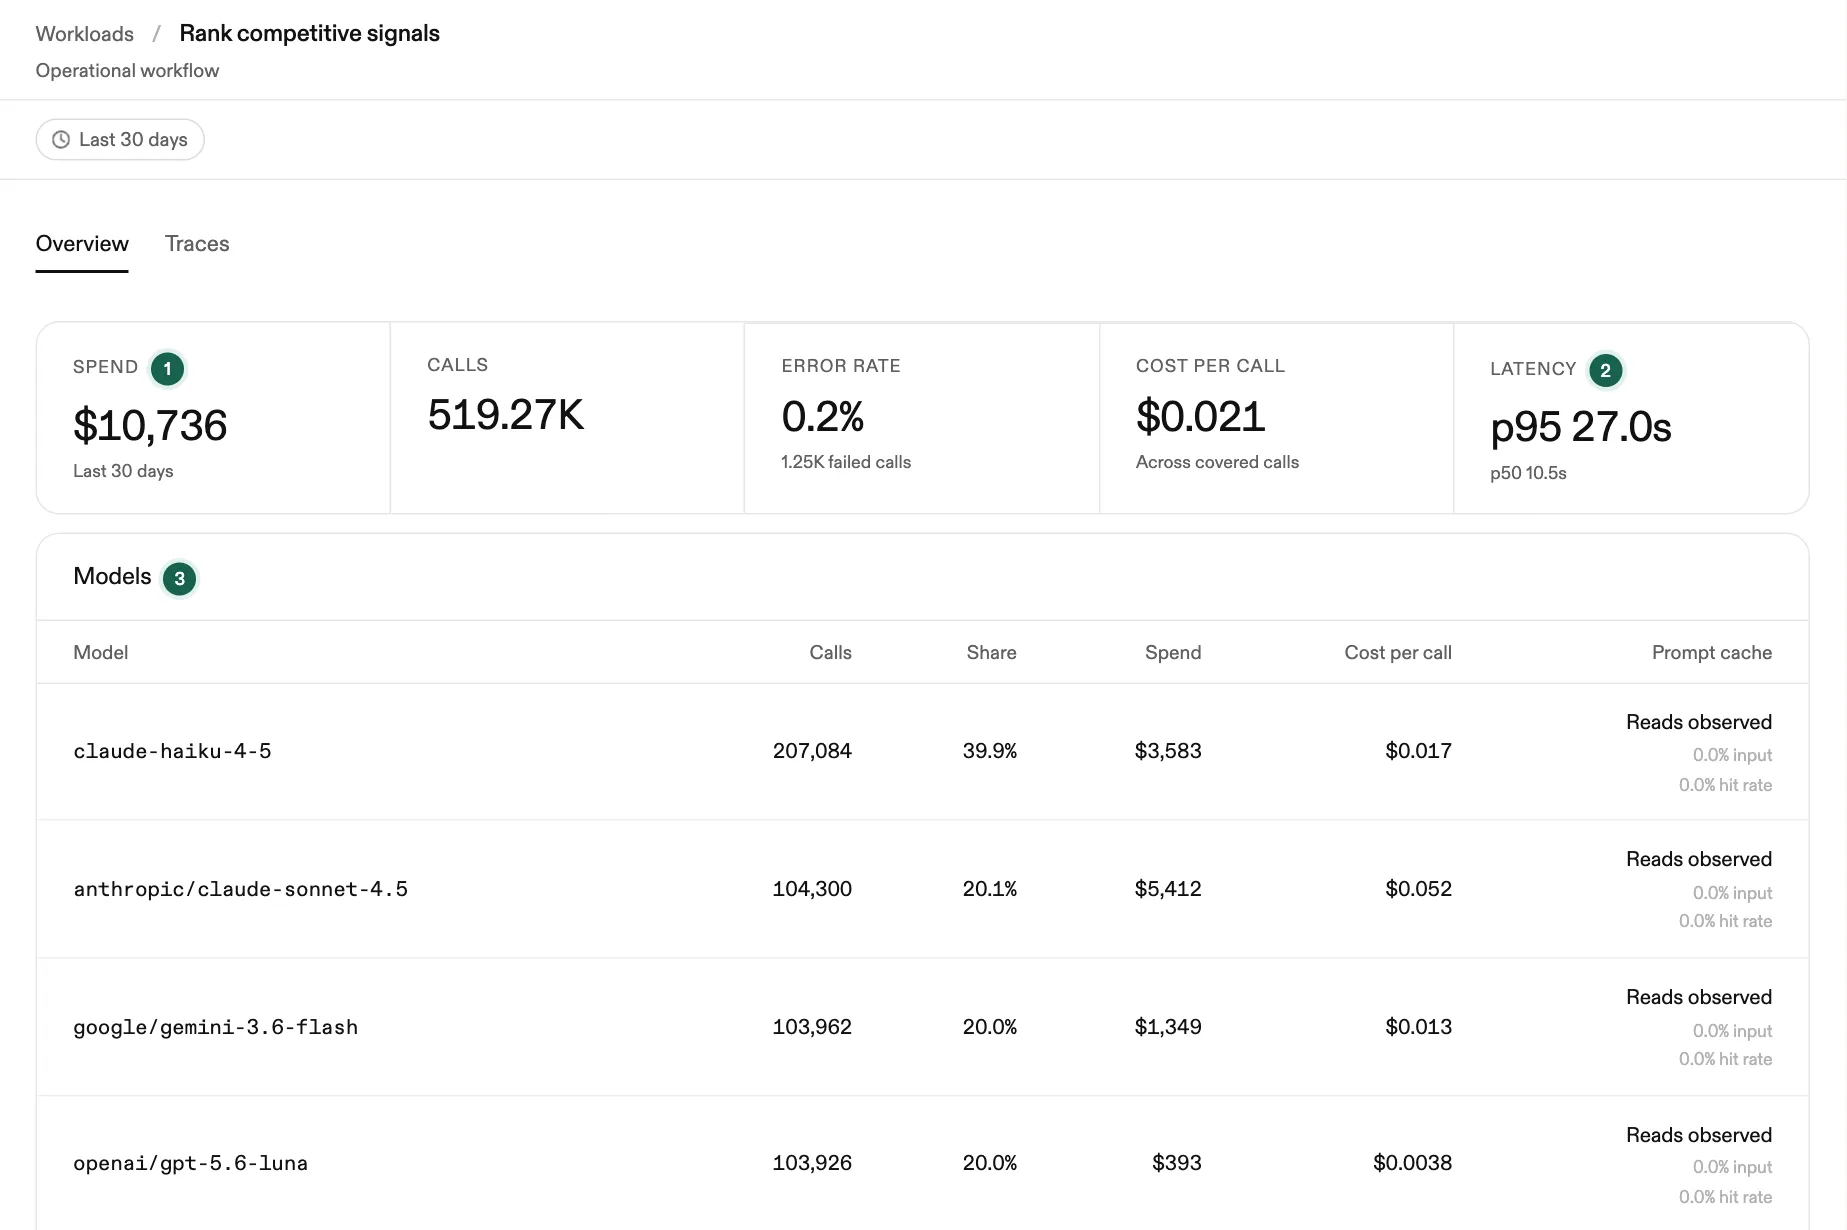
- Spend: $10,736 across 519,270 calls in 30 days, this workflow alone.
- Latency: a typical call takes 10.5 seconds (p50), and the slowest 5% take more than 27 seconds (p95).
- Models: four models share the traffic. Cost per call runs from $0.0038 on GPT-5.6 Luna to $0.052 on Claude Sonnet 4.5, a fourteen-fold spread for the same job.
With your traffic: name your first route to tag a workflow explicitly.
3. What should we change?
Section titled “3. What should we change?”Find · Opportunities
Metergraph explores ways to optimize your traffic automatically: cheaper models, shorter prompts, caching and more. For each promising opportunity it replays a sample of the workload’s real requests, grades the answers against what production returned, and keeps the changes that hold up. Opportunities lists what it found.
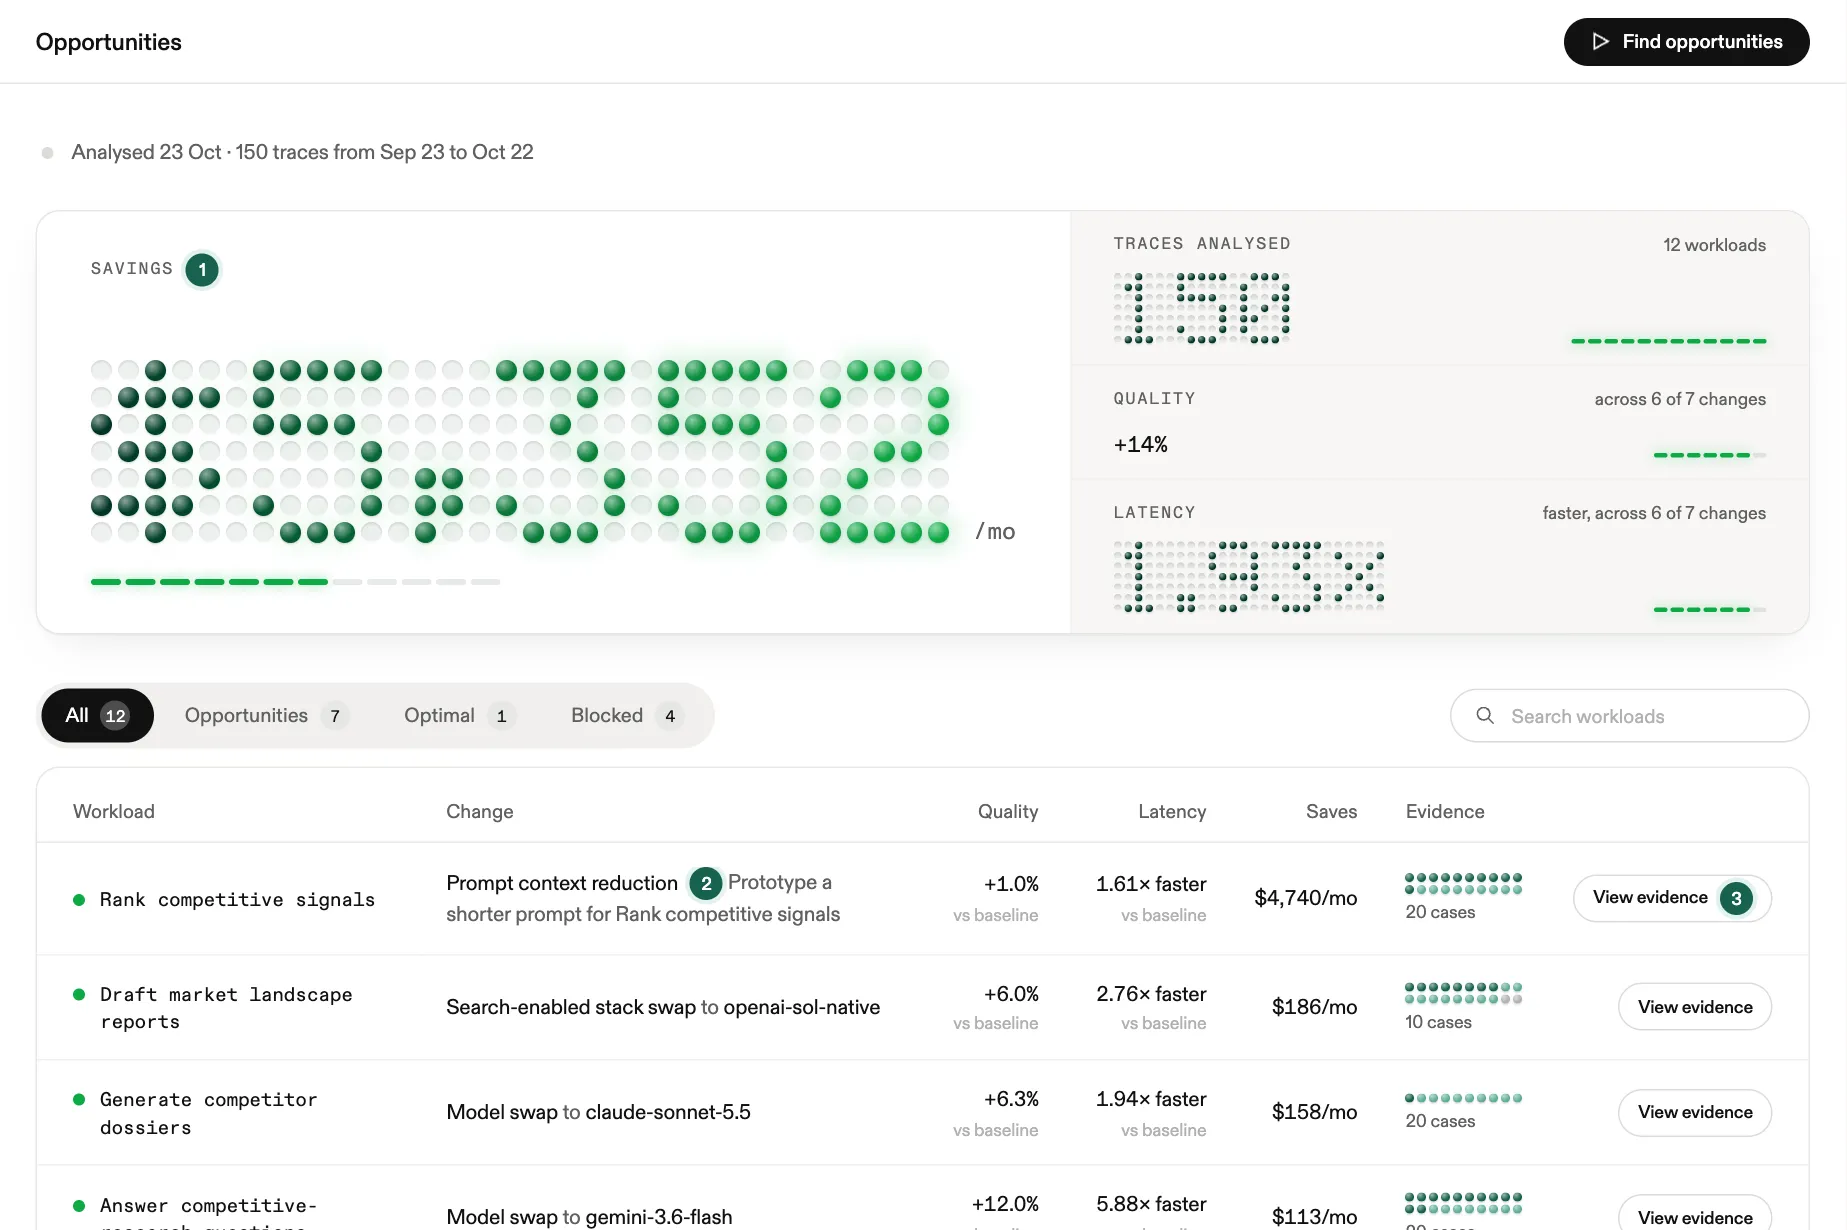
- Savings: what the recommended changes would save each month, projected from the workload’s real volume.
- The change: for Rank competitive signals, a shorter prompt. It saves $4,740 a month, with quality up 1% and calls 1.61 times faster.
- Evidence: the cases the recommendation rests on. View evidence opens each one: the request, what production answered, what the change answered, and the grade.
With your traffic: run your first analysis, or read how analysis works.
4. Will it hold up on our traffic?
Section titled “4. Will it hold up on our traffic?”Validate · Experiments
Before switching, run the candidates on recent calls side by side. Here the team tests its website-audit workflow, which runs on Claude Haiku 4.5, against GPT-5.6 Luna and Gemini 3.6 Flash.
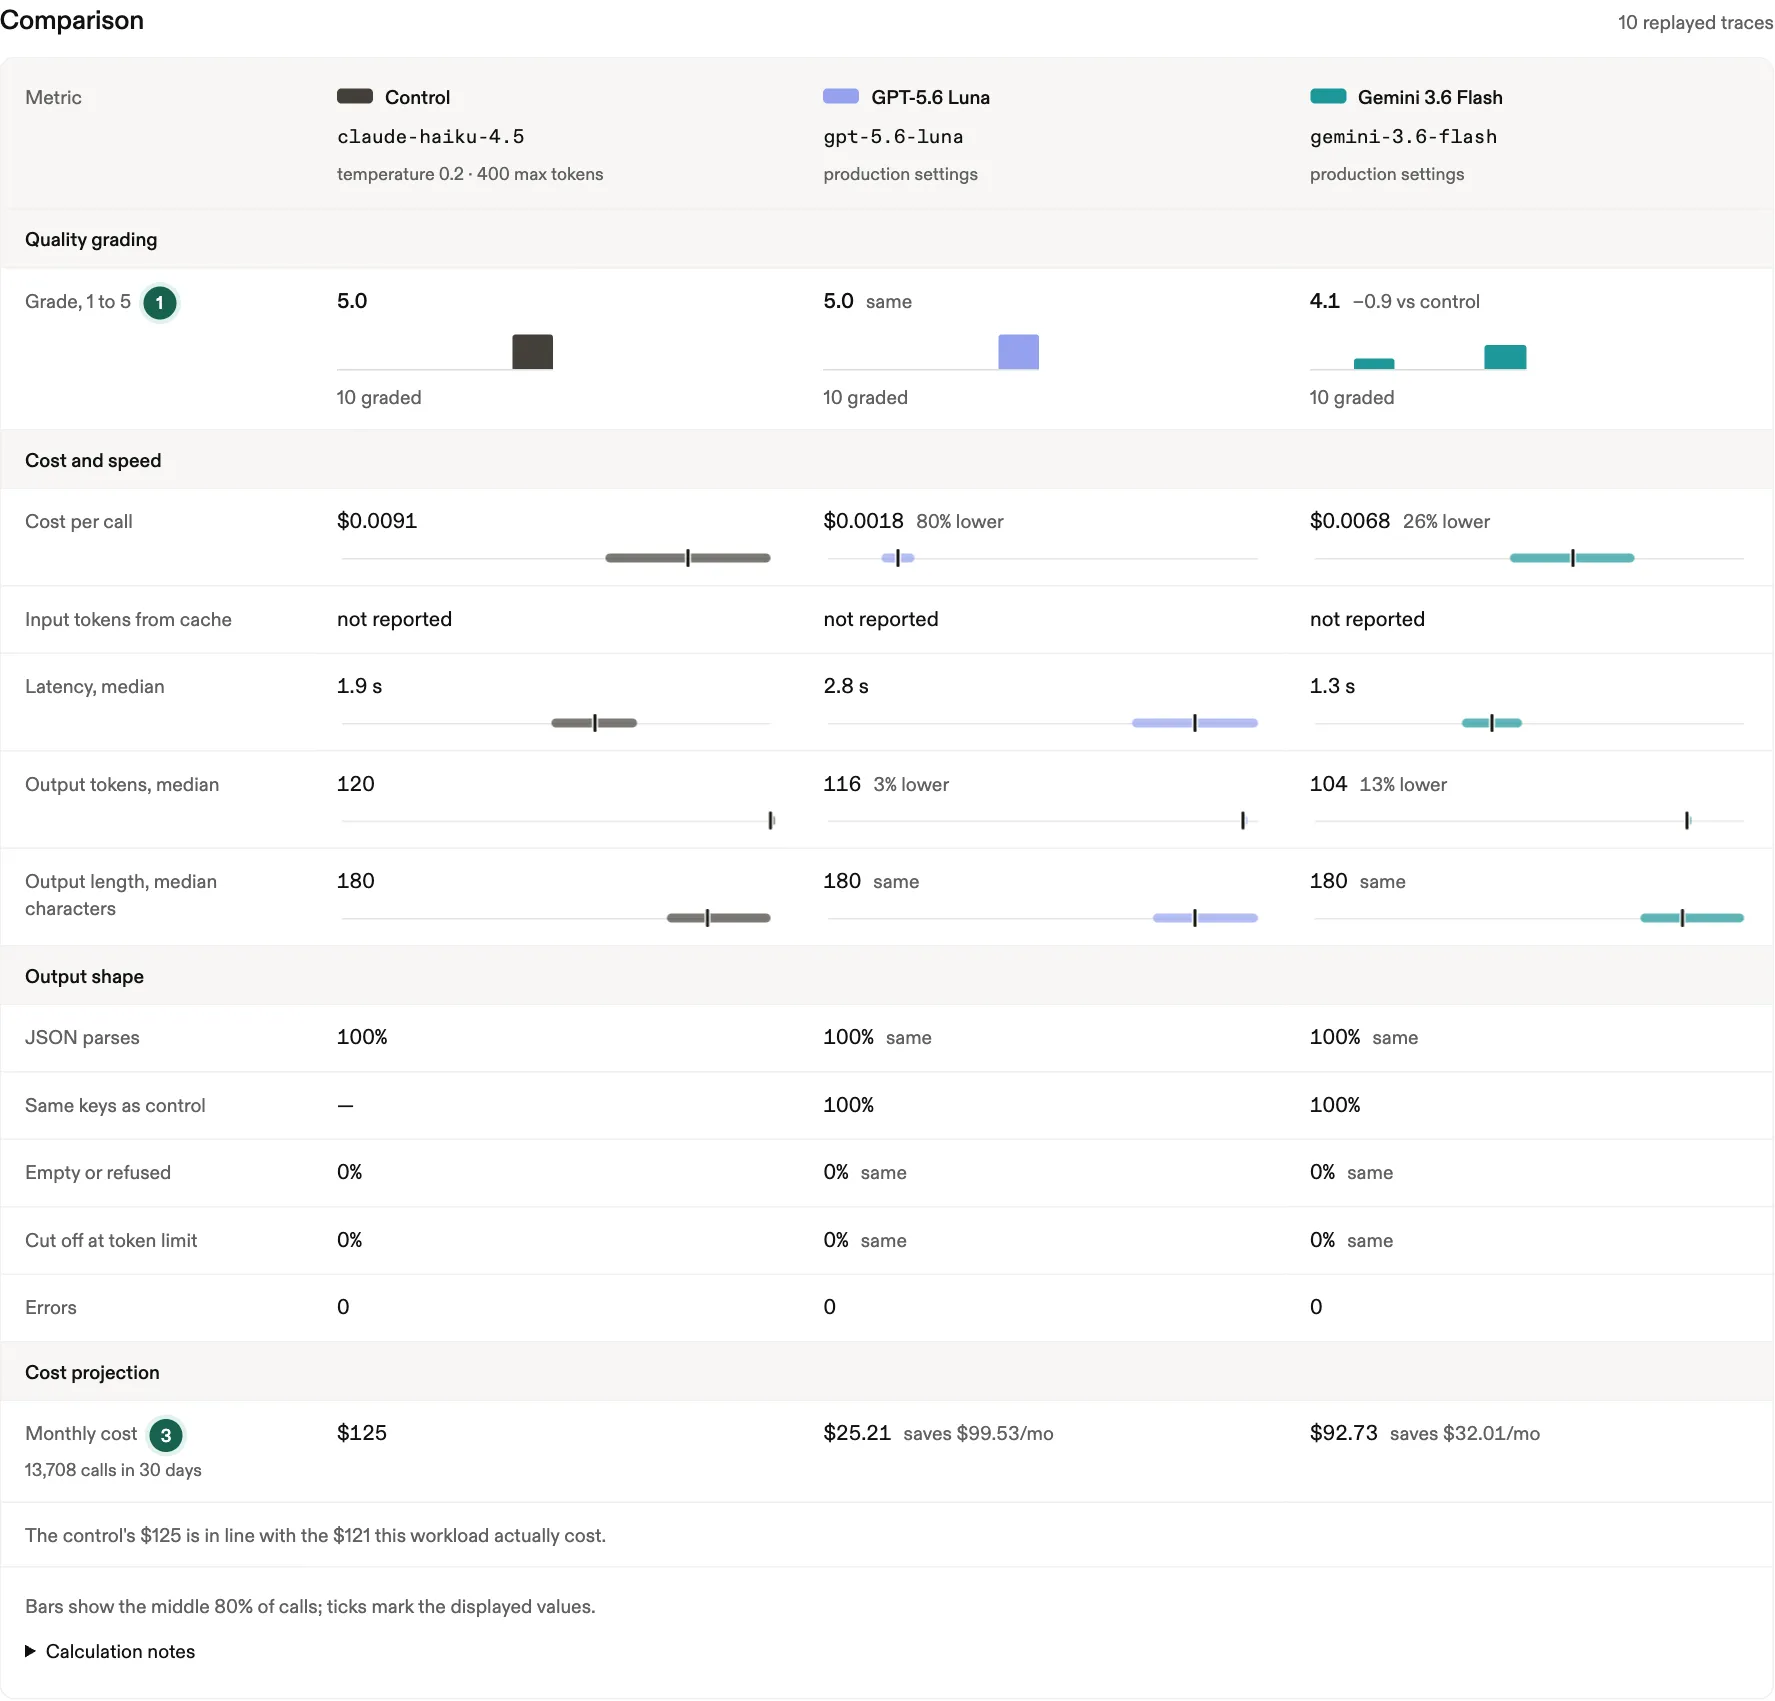
- Grade: an AI judge grades every answer against what production returned. Luna scores 5.0, the same as production. Flash drops to 4.1: it gets three priorities wrong.
- Cost per call: Luna is 80% cheaper than production.
- Monthly cost: on this workflow’s real volume, Luna saves $99.53 a month, in line with what Opportunities predicted.
An experiment can start from an opportunity: Validate on recent traffic opens one with the recommended model already chosen.
Build evals that last
Section titled “Build evals that last”An experiment answers one question once. Evals keep answering it. Build a dataset of reference cases from your own traces, save the checks that matter as a suite in the Evaluation library, and read how each candidate did on Suite results. If you already grade with Langfuse, reuse those judges.
With your traffic: build a dataset or judge swaps with Langfuse evals.
5. How do we catch problems in production?
Section titled “5. How do we catch problems in production?”Protect · Alerts
Traffic, prices and models keep changing after a fix ships. Alerts watches every workflow in production for unusual spend, cost drift, failures, retries, latency changes and template changes.
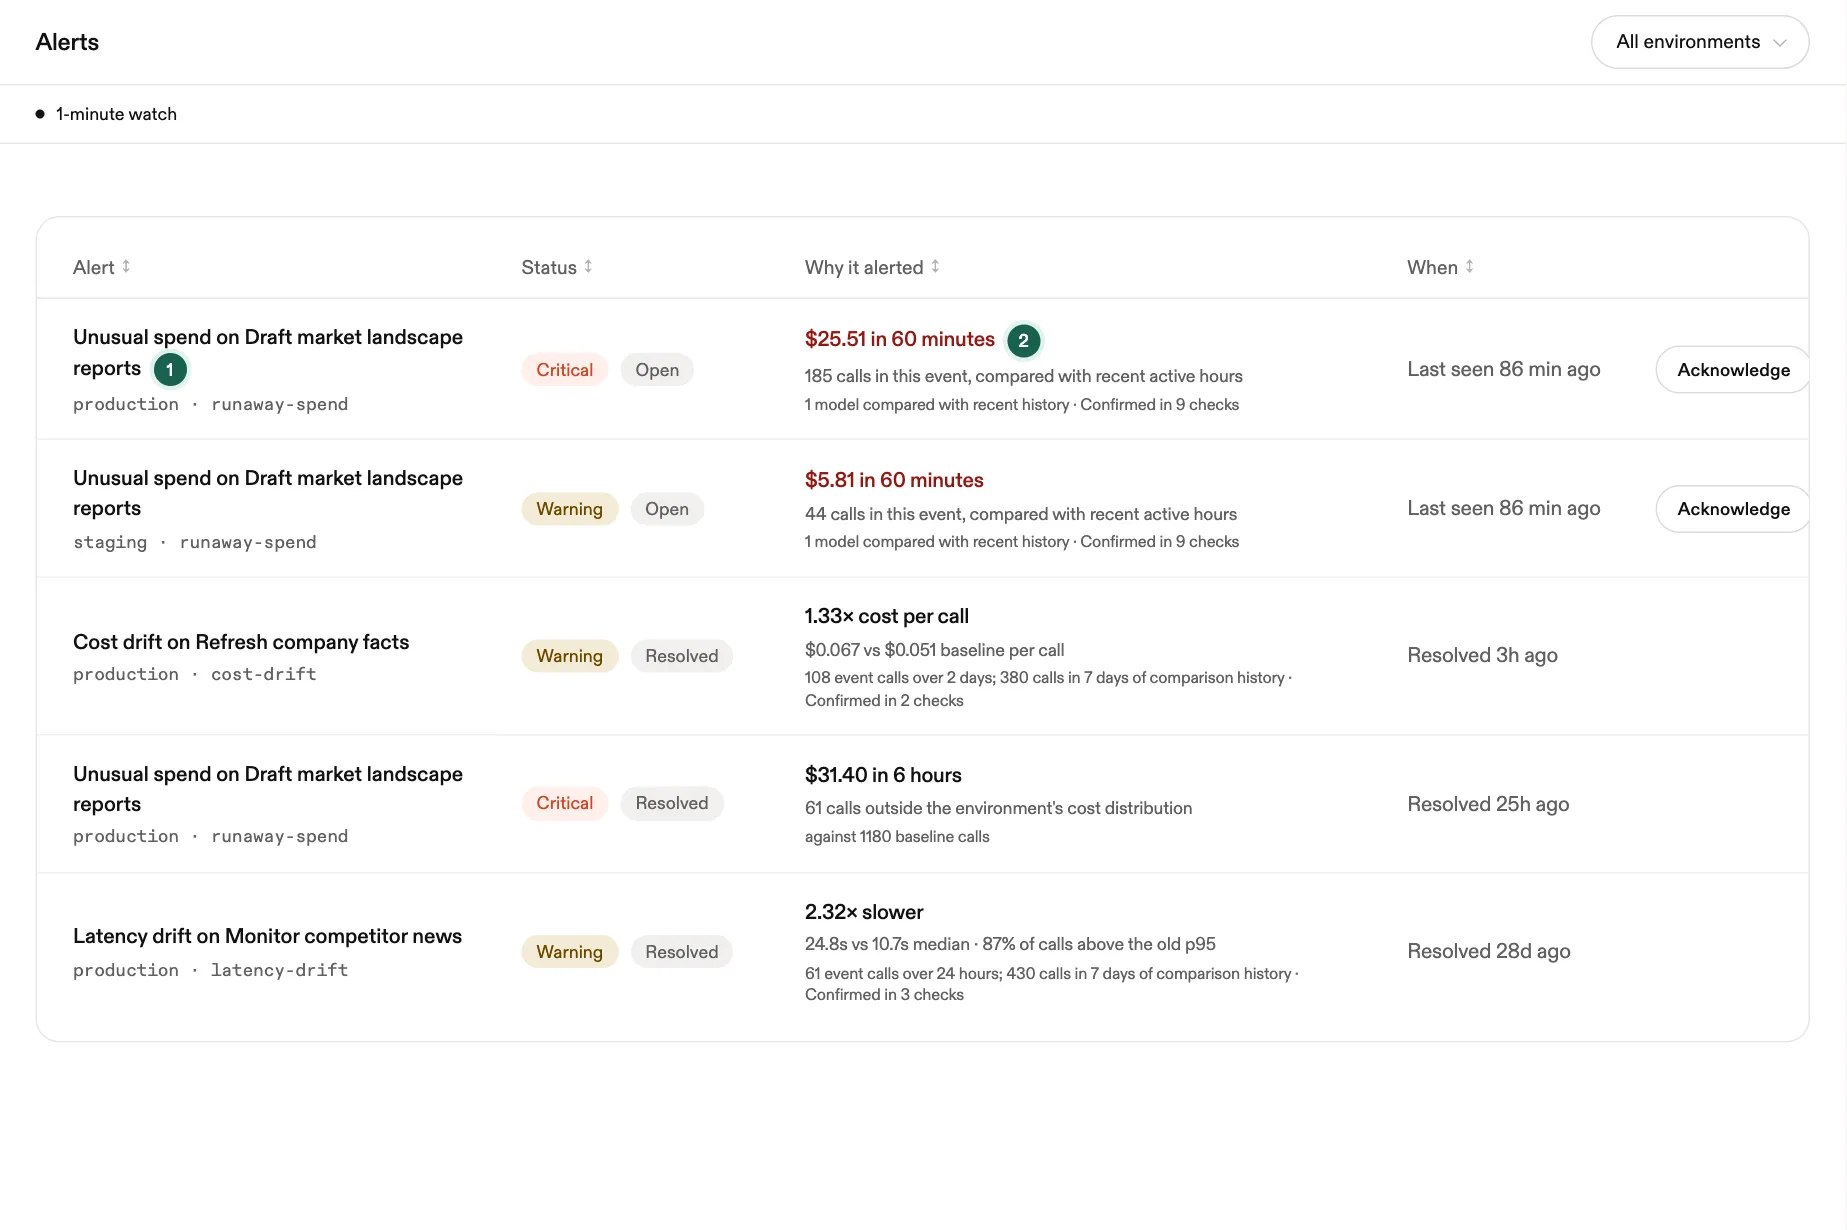
- What moved: unusual spend on Draft market landscape reports, in production, marked critical.
- Why it alerted: $25.51 in one hour across 185 calls, well above the workflow’s recent active hours.
With your traffic: set up alerts and choose where they are delivered.
Ship the fix
Section titled “Ship the fix”When a change has held up, approve it in the dashboard and MetergraphBot opens a pull request for your team to review. Or let your coding agent apply it over MCP.
Keep learning from your traffic
Section titled “Keep learning from your traffic”Shipping a fix is not the end. Metergraph keeps learning from your traffic as it arrives, and prices and models keep changing, so the next opportunity is already forming. The same five steps find it: spot where the money goes, understand the workflow, find the change, validate it, and catch problems in production.
Start with your traffic
Section titled “Start with your traffic”Metergraph Cloud is at app.metergraph.dev. Local and BYOC deployments show the same pages at the host you configured.
Looking for trace filters, pricing coverage, keys, the Batch API or settings? See the Dashboard reference.